
Effective app scalability planning comes down to four decisions made early: define your scale units and SLOs, choose an architecture pattern that fits your team's current maturity, instrument observability before you need it, and run capacity tests before traffic demands it. Get those four right and every growth spike becomes a planned event rather than a crisis.
Your 4-step blueprint:
- Define scale units and SLOs. Partition your app into logical groups of interdependent components that scale together, then set concrete latency and error-rate targets for each.
- Pick an architecture pattern. Start with a modular monolith and clear domain boundaries; split services only when traffic data justifies it.
- Instrument observability first. Add metrics, logs, and distributed tracing before your first production deploy, not after your first outage.
- Run capacity tests and set autoscaling policies. Validate your provisioning model under synthetic load, then configure autoscale bounds driven by real signals.
Prioritization rule: startups should nail observability and a clean modular boundary first; enterprise teams should prioritize autoscaling policy design and multi-region capacity modeling from day one.
Key Takeaways
Effective app scalability planning is a data-driven engineering discipline: define scale units and SLOs first, instrument observability before launch, validate with load tests, and let traffic data drive every architectural split.
| Point | Details |
|---|---|
| Define scale units early | Partition components into logical groups that scale together to avoid noisy-neighbor effects and standardize provisioning. |
| Instrument observability first | Add metrics, logs, and OpenTelemetry tracing before your first production deploy, not after your first outage. |
| Run capacity calculations | Convert peak RPS and per-instance benchmarks into concrete min/max replica counts before you write infrastructure code. |
| Autoscale on multiple signals | Build policies using CPU, RPS, and queue depth together; treat autoscaling as a cost-management tool, not a safety net. |
| Proud Lion Studios | Delivers mobile and backend scalability from day one, including capacity modeling, Kubernetes orchestration, and Firebase monitoring. |
Table of Contents
- What does "app scalability" actually mean for capacity planning?
- Vertical vs. horizontal scaling: how do you choose?
- Core mechanisms that make apps scale
- How to build a capacity model with real numbers
- What to instrument and how to validate your capacity plan
- A phased implementation roadmap
- Antipatterns and trade-offs you must accept
- An applied checklist you can copy today
- How do you handle stateful components in a scalable architecture?
- What we have learned building scalable apps from day one
- Proud Lion Studios builds scalable apps that grow with your business
- Sources
What does "app scalability" actually mean for capacity planning?
Scalability is the ability of a system to handle increasing load by adding resources, without degrading reliability or inflating cost disproportionately. The NIST Definition of Cloud Computing (SP 800-145) frames this through the lens of on-demand resource pooling and rapid elasticity, which is the vocabulary you need when making cloud-based scaling decisions.
The measurable dimensions that feed a capacity model are:
- Requests per second / transactions per second (RPS/TPS). The raw throughput your backend must sustain at peak.
- Concurrent sessions. How many users hold open connections simultaneously, which drives connection pool sizing and WebSocket capacity.
- Data growth rate. Row count, object storage volume, and write IOPS growing month over month.
- Storage I/O. Read and write throughput to databases and object stores under peak load.
- Geographic distribution. Latency budgets change dramatically when users span multiple continents, requiring edge caching or multi-region deployments.
Scalability planning and performance optimization overlap but are not the same problem. Performance optimization reduces the resources a single request consumes. Scalability planning determines how many requests your system can handle before it needs more resources. Both matter: a poorly optimized request burns capacity faster, which means your scaling thresholds trigger sooner and cost more. The NIST Cloud Computing Reference Architecture (SP 500-292) provides the service orchestration vocabulary that ties these two concerns together at the infrastructure layer.
Vertical vs. horizontal scaling: how do you choose?
Vertical scaling adds CPU, RAM, or faster storage to an existing instance. It buys you simplicity: no distributed coordination, no session-sharing problem, no network hops between services. The ceiling is real, though. Every cloud provider has a largest instance type, and resizing usually requires a restart, which means downtime unless you have a standby.
Horizontal scaling adds more instances behind a load balancer. It gives you elasticity and resilience: one node failing does not take down the service. The cost is distributed complexity, including session state management, distributed transactions, and more moving parts to observe.
Decision boundaries:
- Projected concurrent users under ~500 and team size under 5 engineers. Vertical scaling is almost always the right call. The operational overhead of horizontal coordination is not worth it yet.
- Regulatory or ACID constraints. If your data layer requires strict transactional consistency across every write, horizontal scaling of the database tier demands careful design (distributed transactions or saga patterns) that adds months of engineering time.
- Team operational maturity. Horizontal scaling at the application tier is straightforward; horizontal scaling of stateful components (databases, caches, queues) requires the team to understand replication lag, split-brain scenarios, and failover procedures.
Pro Tip: A modular monolith with clean domain boundaries almost always beats early microservices decomposition. You get the architectural clarity of service boundaries without the distributed systems tax. When a single service genuinely needs independent scaling, extract it then, with traffic data to justify the decision.
Core mechanisms that make apps scale
These are the techniques engineers actually reach for, in roughly the order you should consider them.
Stateless services and load balancing. Design every application tier to hold no session state in memory. Store sessions in Redis or a managed session store so any instance can serve any request. AWS Elastic Load Balancing and similar tools then distribute traffic without sticky sessions, which lets you add or remove instances freely.
Caching layers. Three tiers matter:
- In-process cache (local memory): fastest, but not shared across instances and lost on restart.
- Distributed cache (Redis, Memcached): shared across all instances, reduces database round-trips dramatically, and handles millions of operations per second. Redis also supports pub/sub and sorted sets that unlock leaderboard and rate-limiting patterns.
- CDN edge caching (Cloudflare): serves static assets and cacheable API responses from edge nodes close to users, cutting origin load and reducing latency for geographically distributed users.
Asynchronous processing. Offload work that does not need a synchronous response: image processing, email delivery, report generation, blockchain transaction submission. Message queues (AWS SQS, RabbitMQ) and event streams (Apache Kafka) decouple producers from consumers, absorb traffic spikes, and let you scale worker pools independently of your web tier.
Database strategies. Read replicas handle read-heavy workloads without touching the primary. Sharding or horizontal partitioning distributes data across multiple database nodes by a partition key (user ID, tenant ID, geographic region). CQRS (Command Query Responsibility Segregation) separates the write model from the read model, letting each scale independently. PostgreSQL handles both read replicas and logical replication well; Aerospike is purpose-built for high-throughput, low-latency key-value and document workloads where PostgreSQL's row-locking overhead becomes a bottleneck. Eventual consistency is the trade-off you accept when you shard or replicate: plan for it explicitly rather than discovering it in production.
Serverless vs. containers vs. VMs. Serverless (AWS Lambda, Google Cloud Functions) scales to zero and handles bursty, unpredictable traffic with no provisioning overhead, but cold starts add latency and execution quotas cap long-running jobs. Containers orchestrated by Kubernetes give you fine-grained control over resource limits, rolling deploys, and horizontal pod autoscaling, at the cost of cluster management complexity. VMs remain the right choice for workloads with predictable, sustained load where you want the lowest per-unit compute cost and full OS control. The NIST cloud service model definitions (IaaS/PaaS/SaaS) map directly to these three deployment choices.
How to build a capacity model with real numbers
A scale unit is a logical group of interdependent components that you provision, deploy, and validate together. The Azure Well-Architected Framework recommends scoping components into scale units to avoid noisy-neighbor effects and to standardize how you provision and test each tier. A typical hierarchy: a single microservice pod is the smallest unit, a Kubernetes node pool is the next, and a regional deployment stamp is the largest.
Capacity model inputs:
- Peak RPS (from analytics or load tests)
- Daily active users (DAU) and session length
- Average and p95 payload sizes
- Month-over-month growth rate
- Target p95 latency SLO (e.g., 200ms)
- Per-instance throughput benchmark (requests/second at target latency)
Example calculation. Suppose your web tier handles a moderate number of requests per second per instance at a target percentile latency, your peak demand is several times higher, and you want a reasonable headroom percentage:
- Required instances at peak: 400 / 80 = 5 instances
- With 25% headroom: ceil(5 × 1.25) = 7 instances (autoscale max)
- Autoscale minimum: 3 instances (covers baseline traffic, keeps cold-start risk low)
Pro Tip: Measure how long a scale-out operation actually takes, from trigger to a new instance passing health checks. The Azure Well-Architected Framework flags this as an operational metric in its own right. If your scale-out takes 4 minutes and your traffic spike peaks in 2, autoscaling alone cannot protect you: you need pre-warming or a larger minimum floor.
What to instrument and how to validate your capacity plan
Scalability planning without observability is guesswork. Android Developers' performance guidance notes that without logs, metrics, and traces, teams waste significant time diagnosing whether an issue is in app code, the database, or an external API.
Core SLIs to track:
- Latency: p50, p95, p99 per endpoint
- Error rate: 5xx responses as a percentage of total requests
- Throughput: RPS/TPS at the load balancer and at each service
- Queue depth: messages waiting in each async queue
- CPU and memory utilization per instance and per node
- Storage I/O: read/write IOPS and disk throughput
Tracing and logs. Instrument with OpenTelemetry from day one. Teams that do this can trace a single request across every service hop and find root causes in minutes rather than hours. Attach a trace ID to every log line so you can correlate logs and traces without manual searching.
Tools:
- Prometheus and Grafana for metrics collection and dashboards
- OpenTelemetry SDKs for distributed tracing across services
- Firebase Performance Monitoring for mobile and web: it auto-collects startup time, HTTP network request traces, and lets you filter by app version and country, which is invaluable for catching regressions after a release
- Xcode Instruments for native iOS profiling, following Apple's measure-change-implement-compare cycle
Load-testing methodology:
- Define realistic user scenarios (login, browse, checkout, API call patterns).
- Run a baseline test at expected average load to establish your p95 latency floor.
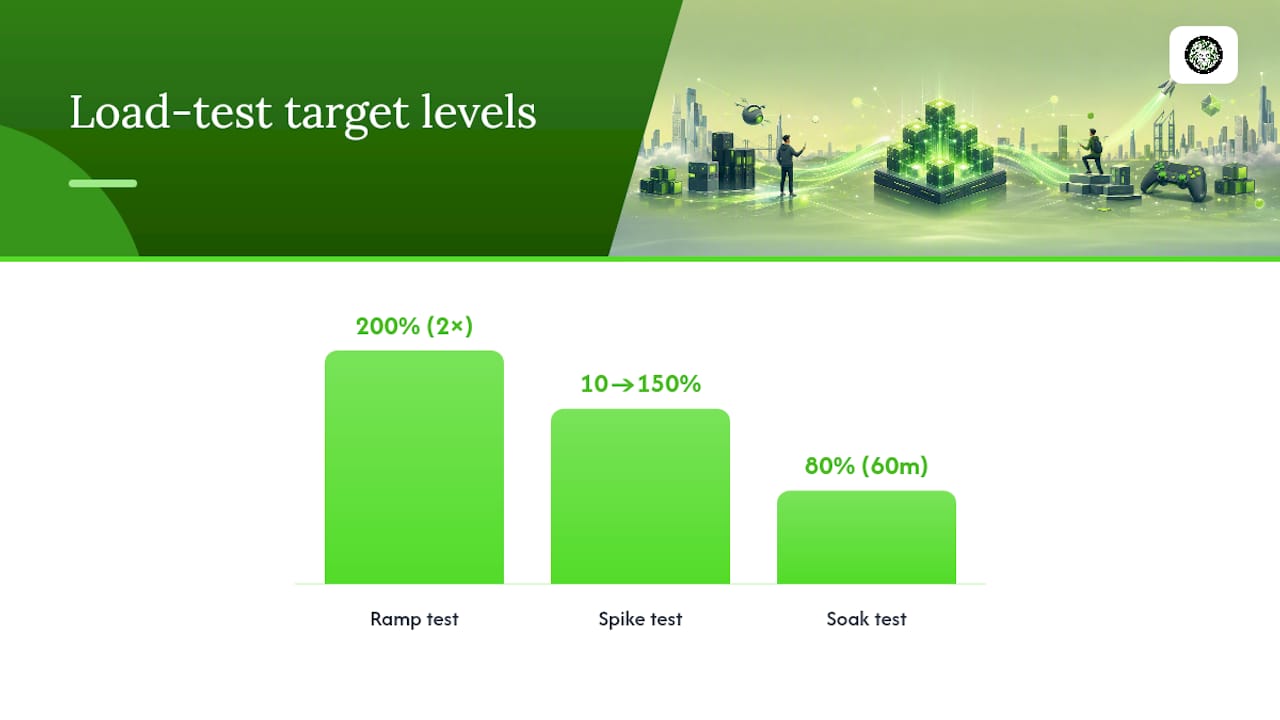
- Ramp to 2× peak load and verify autoscaling triggers correctly.
- Run a spike test: jump from 10% to 150% of peak in 30 seconds.
- Run a soak test at 80% of peak for 60 minutes to catch memory leaks and connection pool exhaustion.
- Run chaos tests: kill one instance mid-test and verify traffic reroutes without error spikes.
Tools: k6 and Locust both work well for synthetic load generation. k6's JavaScript-based scripting makes scenario definition fast; Locust's Python base is easier for teams already writing Python services.
Alert thresholds (starting points, tune to your SLOs):
- p95 latency > 300ms for 2 consecutive minutes: page on-call
- Error rate > 1% for 1 minute: page on-call
- Queue depth > 500 messages for 5 minutes: warning alert
- CPU > 80% for 3 minutes: trigger scale-out review
Google Cloud's patterns for scalable apps recommend building autoscaling policies from multiple signals, not just CPU, and treating scalability as a cost-management strategy: systems should consume only the resources current demand actually requires.
A phased implementation roadmap
Phase 0: Pre-launch / MVP (Weeks 1–6)
- Size your initial vertical instance based on your capacity model's minimum replica count.
- Add structured logging, basic Prometheus metrics, and a dashboard showing latency and error rate.
- Define clean module boundaries by business domain, even inside a monolith.
- Write your first load test scenario and run it before launch.
Go/no-go trigger: p95 latency under SLO at 2× expected launch traffic.
Phase 1: Early growth (Months 2–4)
- Add Redis caching for your highest-read endpoints.
- Spin up read replicas for your primary database (PostgreSQL works well here).
- Configure basic horizontal pod autoscaling in Kubernetes, driven by CPU and RPS.
- Set up CI/CD with canary deploys so you can roll back a bad release in under 5 minutes.
Go/no-go trigger: autoscaling validated under load test; canary deploy tested end-to-end.
Phase 2: Scale (Months 5–12)
- Introduce sharding or partitioning for your highest-write database tables.
- Deploy to a second region; use Cloudflare or a global load balancer to route traffic.
- Implement advanced autoscaling policies using queue depth and custom business metrics alongside CPU.
- Add async processing for all non-critical user-facing operations.
Go/no-go trigger: multi-region failover tested; p99 latency within SLO under regional failure simulation.
Cost levers to track at each phase: instance count × hourly rate, data transfer costs (especially cross-region), managed service fees (Kubernetes control plane, managed databases), and CDN bandwidth.
Antipatterns and trade-offs you must accept
The most expensive mistakes in scalability are not technical failures. They are architectural decisions made without data.
- Noisy neighbor in multi-tenant setups. One tenant's heavy workload degrades performance for others when they share a database, cache, or queue. Mitigation: use scale units with per-tenant resource quotas, or isolate high-volume tenants to dedicated infrastructure.
- Premature microservices decomposition. Splitting a monolith before you understand your service boundaries creates a distributed monolith: all the complexity of microservices with none of the independent deployability. Modular boundaries by business domain with a migration path beats early decomposition every time.
- Skipping observability until after an outage. Without metrics and traces in place before the incident, you are debugging blind. The fix costs 10× more time than the initial instrumentation would have.
- Over-provisioning. Running at 20% CPU utilization because you fear a spike wastes real money. Autoscaling tuned to real-time metrics is the answer, not a permanently large fleet.
- Under-provisioning. Setting autoscale minimums too low means scale-out latency (the time to bring a new instance healthy) exposes users to degraded performance during the ramp-up window.
Red flags in production: p95 latency trending up week over week without a traffic increase; queue depth growing faster than worker throughput; database connection pool exhaustion appearing in logs; memory usage climbing steadily without a corresponding traffic increase (memory leak).
An applied checklist you can copy today
SLO template:
- Service: [name]
- Latency SLO: p95 < [X]ms over a 30-day rolling window
- Error rate SLO: < [Y]% of requests return 5xx over a 30-day rolling window
- Alerting action: page on-call when SLO burn rate exceeds 2× for 1 hour
Autoscaling policy (Kubernetes HPA example signals):
- Scale out when: CPU > 70% OR RPS per pod > [benchmark RPS × 0.8] for 2 minutes
- Scale in when: CPU < 40% AND RPS per pod < [benchmark RPS × 0.4] for 5 minutes
- Minimum replicas: [capacity model minimum]
- Maximum replicas: [capacity model maximum + 20% buffer]
Capacity model input checklist:
- Peak RPS from analytics or prior load tests
- DAU and average session duration from product analytics
- p95 payload size from APM or network traces
- Month-over-month growth rate from business projections
- Per-instance throughput benchmark from load tests
- Target p95 latency SLO from product requirements
Teams that follow this checklist before writing a single line of infrastructure code consistently avoid the most expensive replatforming scenarios. The scalable app architecture guidance from Editorialge reinforces the same pattern: prioritize the user paths that affect retention, add caches and read replicas for early wins, and defer full rewrites until traffic data demands them.
Pro Tip: Source your growth rate number from two places: your product analytics and a conservative business projection. Use the higher of the two in your capacity model. The cost of a slightly over-provisioned system is always lower than the cost of an emergency replatform.
How do you handle stateful components in a scalable architecture?
Stateful components, databases, caches, message queues, and session stores, are the hardest part of scaling because you cannot simply add instances and let a load balancer distribute requests. Each approach below addresses a specific statefulness problem.
Externalize all session state. Move session data from application memory to Redis or a managed session store. Every application instance becomes stateless and interchangeable, which is the prerequisite for horizontal scaling.
Database replication and read/write splitting. Direct writes to the primary and reads to one or more replicas. PostgreSQL's streaming replication handles this well. Accept that replicas may lag the primary by milliseconds to seconds under heavy write load, and design read paths that tolerate eventual consistency where appropriate.
Sharding by a natural partition key. Partition your data by user ID, tenant ID, or geographic region. Each shard handles a subset of the total data volume, so write throughput scales horizontally. The trade-off: cross-shard queries become expensive, so your data model must minimize them.
Distributed caching with Redis. Redis handles both caching and lightweight coordination (distributed locks, pub/sub, rate limiting). For scalable mobile and web apps, a Redis cluster with read replicas can serve millions of cache operations per second while keeping your database load flat.
Message queues for async state transitions. Instead of writing state changes synchronously across multiple services, publish an event to a queue (AWS SQS, Kafka) and let consumers process it asynchronously. This decouples services and makes the system resilient to downstream slowdowns.
Security at scale. Rate limiting at the API gateway (Cloudflare, AWS API Gateway) protects stateful backends from abuse and DDoS amplification. Token-based authentication (JWT with short expiry, refresh token rotation) scales without server-side session storage. At high scale, centralize authentication through a dedicated identity service rather than embedding auth logic in every microservice.
What we have learned building scalable apps from day one
The conventional wisdom says "design for scale from the start." The reality is more nuanced. Designing for scale from day one does not mean deploying Kubernetes and a 12-service microservices mesh on day one. It means making decisions that do not foreclose scaling options later: clean module boundaries, stateless application tiers, and observability wired in before the first user arrives.
The single most expensive mistake we see teams make is skipping the capacity model. They deploy, watch traffic grow, and then scramble to add read replicas and caching under live production pressure. That scramble costs three to five times more in engineering hours than a two-day capacity modeling exercise would have.
The second lesson: autoscaling is not a substitute for a capacity model. Google Cloud's scalability patterns frame scalability as a cost-management strategy, and that framing is exactly right. Autoscaling tuned to real signals prevents waste; autoscaling without a model just automates over-provisioning.
When to call in external experts: when your team is about to make an irreversible architectural decision (choosing a database engine, committing to a cloud provider, designing a sharding key) and no one on the team has done it before at the scale you are targeting. That is the moment where a few hours of external review saves months of replatforming.
One security note: rate limiting and token management must be part of your scalability plan, not an afterthought. An unprotected endpoint at scale is an attack surface that can take down the entire system.
Proud Lion Studios builds scalable apps that grow with your business
Your capacity model is only as good as the team that implements it. Proud Lion Studios delivers mobile app development for iOS and Android) with scalable backend architecture built in from the first sprint, not retrofitted after launch. Whether you need roadmap planning, a capacity modeling session, or a managed rollout from MVP to multi-region production, we bring the full technical stack: stateless service design, Redis caching, Kubernetes orchestration, and Firebase Performance Monitoring wired in before your first user arrives.
For teams building on blockchain or integrating decentralized backends, our blockchain development services cover scalable ledger architecture and smart contract engineering alongside your mobile or web frontend. We work with startups and enterprise teams across multiple countries, and every engagement is a custom contract built around your actual traffic projections and growth targets, not a templated package.
Ready to plan your app's growth architecture? Contact Proud Lion Studios to start with a capacity modeling conversation.
Sources
- Mission-critical application design (Azure Well-Architected Framework)
- Patterns for scalable and resilient apps | Cloud Architecture Center | Google Cloud Documentation
- Performance Monitoring | Firebase
- Improving your app’s performance - Apple Developer
- The NIST Definition of Cloud Computing (SP 800-145)
- NIST Cloud Computing Reference Architecture (SP 500-292)
- App Scalability Planning: Designing for Growth from Day One | App Development
- How To Build A Scalable App Architecture From Day One